Your Image to Prompt Output Is Wrong — Fix It in This Order
Nine causes, ranked by how often each one bites, are set out on the prompt to image page. This page keeps the part that is specific to a tool that writes the prompt for you — and the cases where the fix is not in the wording at all.
When the prompt an image to prompt tool hands you renders the wrong picture, the cause is rarely the sentence. The nine causes — checkpoint, the checkpoint's own published settings, verb form, weights inside 0.4–1.6, term order, AND at equal weight, one attribute at a time, sampler, upscaler — are ranked in the order they actually bite on what prompt to image really involves. That page carries the conditions and the thresholds. This one does not repeat them.
What is left here is what that list cannot cover, because none of it is about the wording: where this tool puts its own terms, the parser check for a weight that drifted out of range, and the cases where the description itself is the thing that is wrong. Rewording first is still the most common misdiagnosis in this workflow — a photorealistic checkpoint will not return anime however the request is phrased — but the ranked list above is where to start.
Change one thing per run and revert what did not help. If you change five things and the picture improves, you have learned nothing about which one mattered — and you will hit the same problem again next week with no idea why it went away.
Check your weights instead of guessing at them
Nested parentheses compound, and that is where most out-of-range weights come from: nobody types 1.61, they type five pairs of brackets. Each ( ) level multiplies by about 1.1, each [ ] divides by about 1.1. Run the parser over your prompt and read the actual numbers:
$ node tools/weight-syntax.js --check "(((((a running dog)))))"
out of range: a running dog @ 1.61
These are real outputs from running the parser on nested terms:
| What you typed | Weight | Verdict against 0.4–1.6 |
|---|---|---|
a running dog | 1.00 | inside |
(a running dog) | 1.10 | inside |
((a running dog)) | 1.21 | inside |
(((a running dog))) | 1.33 | inside |
((((a running dog)))) | 1.46 | inside, but close to the line |
(((((a running dog))))) | 1.61 | out of range |
[blurry] | 0.91 | inside |
[[[blurry]]] | 0.75 | inside |
[[[[[blurry]]]]] | 0.62 | inside |
[[[[[[[[[blurry]]]]]]]]] | 0.42 | inside, barely |
[[[[[[[[[[blurry]]]]]]]]]] | 0.39 | out of range — ignored |
The asymmetry is the useful part: strength runs out after five levels, but you need ten levels of weakening before a term is dropped entirely. That is why over-emphasis breaks a picture long before de-emphasis makes a term vanish.
The nesting trap: an outer bracket still multiplies an explicit weight
This one fools people who already know the syntax. Writing (dog:1.3) sets the weight outright — but wrapping that in another pair of parentheses does not leave it alone, it multiplies it:
$ node tools/weight-syntax.js "((dog:1.3))" --to explicit
(dog:1.43)
1.3 became 1.43. Do that twice more and you are past the ceiling without ever having typed a number above 1.6. If you want an exact weight, write it once, at the outermost level, with no brackets around it.
One thing the parser deliberately will not do: NovelAI-style curly braces are read but never assigned a number, because that engine's per-level multiplier is not the same as the WebUI one. They come back as unknown rather than a plausible-looking guess:
$ node tools/weight-syntax.js "((a running dog)), [blurry], (sky:1.3), ((dog:1.3)), {anime style}"
   1.21  a running dog
   0.91  blurry
    1.3  sky
   1.43  dog
unknown  anime style
The order problem is already built into generated prompts
Weight decays left to right, so look at where a generated prompt puts things. The composer builds its list in a fixed sequence — subject, framing, exposure, then the colour line spliced in at position three, then saturation, temperature, contrast, detail and lighting. The palette line therefore sits third, ahead of contrast, detail and everything else. Nobody chose that: the writer splices at index two on every image, so the slot never moves.
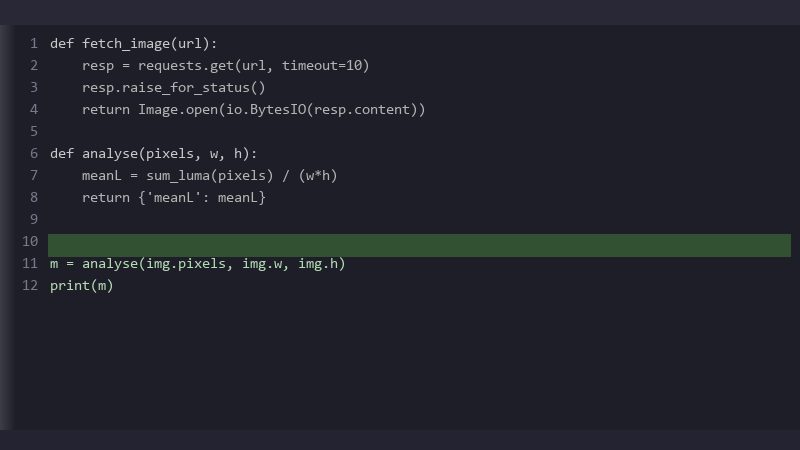
On a frame that is mostly one flat colour that is a problem, and it is measurable. One 800×450 code screenshot came back with charcoal at 0.919 of the frame, forest green at 0.070, slate at 0.011 and grey at 0.000, so the third slot holds dominant palette of charcoal, forest green, slate, grey — a tag for a colour that covers nine tenths of the picture, sitting ahead of the saturation, temperature, contrast and detail phrases.
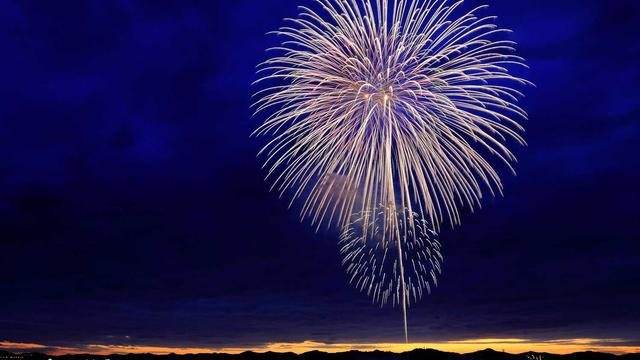
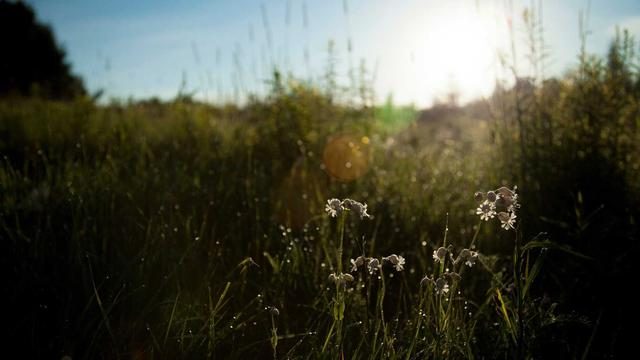
All three images on this page put the palette in the same slot. What changes from image to image is the words inside it and how much of the frame its first colour covers:
| Image | Largest colour bucket | Palette line, as written | Slot 3 sits ahead of | Slots behind it short / medium / long | Palette slot if moved to the end |
|---|---|---|---|---|---|
| night-fireworks 640×360 | navy 0.732 | dominant palette of navy, grey, slate, silver | vivid, saturated colour | 2 / 5 / 7 | 5 / 8 / 10 |
| strong-backlight 640×360 | black 0.577 | dominant palette of black, charcoal, silver, white | vivid, saturated colour | 2 / 5 / 7 | 5 / 8 / 10 |
| text-screenshot 800×450 | charcoal 0.919 | dominant palette of charcoal, forest green, slate, grey | moderately saturated colour | 2 / 5 / 6 | 5 / 8 / 9 |
Cut the line and paste it back at the end and the order changes for everything behind it. The code screenshot at medium length, before and after:
before: widescreen 16:9 composition, dark, low-key lighting, dominant palette
        of charcoal, forest green, slate, grey, moderately saturated colour,
        slightly cool tone, soft, low contrast, clean and minimal, smooth
        surfaces, evenly lit --ar 16:9
after : widescreen 16:9 composition, dark, low-key lighting, moderately
        saturated colour, slightly cool tone, soft, low contrast, clean and
        minimal, smooth surfaces, evenly lit, dominant palette of charcoal,
        forest green, slate, grey --ar 16:9
The two photographs move the same way with their own words in place of charcoal: slot three of eight becomes slot eight of eight at medium length, and three of ten becomes ten of ten at long. The measurements behind all of it are still true — the screenshot really is 92% one flat colour and the fireworks 73% one navy — the palette line just should not be third in line.
When the fix is not in the wording at all
Everything above assumes the prompt describes your picture and the render went wrong. Sometimes the description itself is the thing that is off, and no amount of rewording will touch it.
Three images were run through the analyser — a night fireworks shot, a backlit meadow and a code screenshot — and the subject field came back empty on all three. It is filled in only when a measured threshold is crossed: monochrome share above 0.85, or green or blue dominance above 0.45. The three measured 0.0117, 0.2016 and 0.0222 on monochrome share, so nothing fired. If you feed in a night scene, a backlit photo or a code screenshot and then spend twenty minutes trying to "fix" the colour words, you are fixing the wrong layer — there is no subject in the output to fix. Write your own noun at the front. The light, framing and contrast figures around it are still accurate and still worth keeping.
There is also one defect you can fix by hand in a second. The sentence-shaped variants are built from a template that always opens with A — the article is not chosen for vowel-initial words. It only shows up when your framing phrase itself starts with a vowel, which is how you get A ultra-wide panoramic image. All three samples here measure as widescreen 16:9, so none of them triggers it; if one of your own images does come back headed A ultra-wide, change it to An and move on.
Before any of that: confirm you pasted the right shape
One measurement, four outputs, and they do not accept the same shape. The Midjourney variant is a comma list ending in a parameter; the Stable Diffusion variant opens with quality tags; the flux and DALL·E variants are sentences. Same source image, same numbers:
midjourney : widescreen 16:9 composition, dark, low-key lighting, dominant
             palette of navy, grey, slate, silver, ... light falling on the
             centre with darker edges --ar 16:9
sd         : masterpiece, best quality, widescreen 16:9 composition, dark,
             low-key lighting, ... light falling on the centre with darker edges
flux       : A widescreen 16:9 image. Dark, low-key lighting. The dominant
             colours are navy, grey, slate, silver. ...
dalle      : A widescreen 16:9 image, dark, low-key lighting, with a palette
             of navy, grey, slate, silver. ...
Pasting the Stable Diffusion string into Midjourney — or the reverse — is a format mismatch, not a wording problem, and it will look exactly like a prompt that "came out wrong". Match the target first, then start down the list.
What to do with a prompt you cannot fix
If you have worked the whole list and the result is still wrong, the description is probably measuring something your picture genuinely is. Every value behind every phrase is shown alongside the generated prompt, so you can find the number that produced the wording and argue with that number instead of with the sentence — the cut-offs and the measured values for three real images are laid out in what an image to prompt tool actually measures. For the other direction, words in and picture out, see what actually decides the result in prompt to image.