Get a Usable AI Image Prompt From Any Picture — Three Edits
One picture goes in, four different prompt shapes come out. Here is which one your tool actually wants, the three edits every generated prompt needs before you press generate, and all 480 outputs as a file you can download.
Drop the picture in, read the prompt out, then make three edits before you generate anything: pick the shape your target expects, write your own subject into the front, and check the aspect ratio it handed you. Every other phrase in the output — exposure, contrast, colour temperature, detail level, palette — is computed from your pixels and can go in untouched.
The three edits are ordered by how often they are the thing that ruins the render. Shape mismatch is the most common and the least obvious, because a wrongly-shaped prompt does not fail — it renders something plausible and wrong.
- Match the shape to the target. The generator emits four genuinely different strings for four targets: a comma list ending in
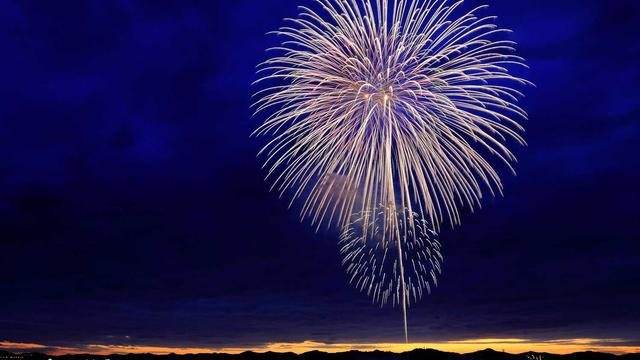
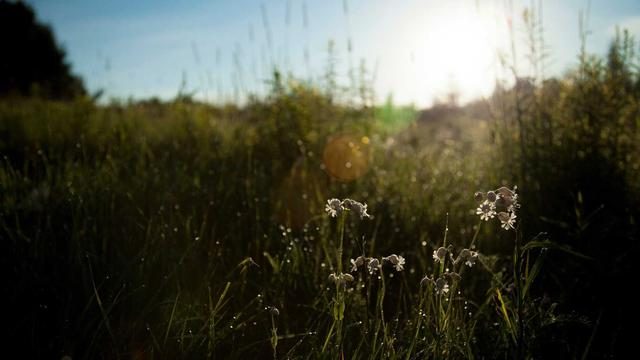
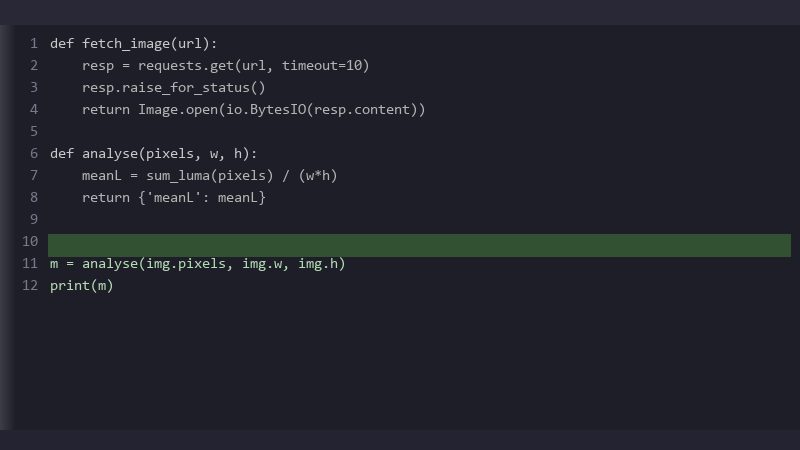
--arfor Midjourney, a comma list opening withmasterpiece, best quality,for Stable Diffusion checkpoints, and two sentence forms for flux and DALL·E. They are not interchangeable. - Write your own subject into the front. Three images were run through it — a night fireworks shot, a backlit meadow and a code screenshot — and the
subjectfield came back empty on all three. It is only filled in when a measured threshold is actually crossed: monochrome share above 0.85, or green or blue dominance above 0.45. The three measured 0.0117, 0.2016 and 0.0222 on monochrome share, so nothing fired, and what you get is a prompt that opens with framing rather than with a thing. Put your own noun in front of it. - Check the aspect ratio it handed you. The
--arvalue is your pixel dimensions reduced by their greatest common divisor and then scaled down if either side exceeds 60. A 640×360 frame divides cleanly by 40 and comes out as16:9; a frame that does not divide neatly gets scaled to the nearest representable pair instead. Confirm it is the canvas you actually want.
Four shapes, one measurement
These are real outputs from one of the three — the night fireworks shot, 640×360 — produced by running the formatter for each of the four targets at the default medium length. Same numbers behind all four — nothing about the measurement changed:
midjourney : widescreen 16:9 composition, dark, low-key lighting, dominant
             palette of navy, grey, slate, silver, vivid, saturated colour,
             cool blue colour temperature, medium contrast, highly detailed
             with intricate texture, light falling on the centre with darker
             edges --ar 16:9
sd         : masterpiece, best quality, widescreen 16:9 composition, dark,
             low-key lighting, dominant palette of navy, grey, slate, silver,
             vivid, saturated colour, cool blue colour temperature, medium
             contrast, highly detailed with intricate texture, light falling
             on the centre with darker edges
flux       : A widescreen 16:9 image. Dark, low-key lighting. The dominant
             colours are navy, grey, slate, silver. Vivid, saturated colour,
             cool blue colour temperature. Highly detailed with intricate
             texture.
dalle      : A widescreen 16:9 image, dark, low-key lighting, with a palette
             of navy, grey, slate, silver. Vivid, saturated colour, cool blue
             colour temperature, highly detailed with intricate texture.
Two structural facts are worth knowing because they explain most surprises. The palette line is spliced into third position in both list-shaped variants, right after subject and framing — it is not appended at the end. And the two sentence-shaped variants carry less: the DALL·E form never receives the evenly lit lighting-distribution phrase at any length, and the flux form only gains it at the long setting.
That last point decides what you can do with a line you already have. If you want the same photograph written for a different target, you do not have to run the tool again — you can rewrite it from the line alone, but only in the directions where the source line already carries every value the target reads. Twenty of the thirty-six directions work exactly, and the sixteen that do not are missing a named value rather than being approximate: see what one image to prompt line can carry into another shape.
What came back from three real images
| Source | Pixels | --ar | Framing phrase | Palette words | Mono share |
|---|---|---|---|---|---|
| night-fireworks.png | 640×360 | 16:9 | widescreen 16:9 | navy, grey, slate, silver | 0.0117 |
| strong-backlight.png | 640×360 | 16:9 | widescreen 16:9 | black, charcoal, silver, white | 0.2016 |
| text-screenshot.png | 800×450 | 16:9 | widescreen 16:9 | charcoal, forest green, slate, grey | 0.0222 |
The length of the finished string shifts with the length setting far more than with the picture. Across all three images and all three lengths, the Midjourney variant ran 158–319 characters, Stable Diffusion 175–336, flux 100–273 and DALL·E 93–219. The spread between lengths inside one target is far wider than the spread between pictures — length decides how many measured fields get included, and that is what moves the count.
The Midjourney variant is the one people ask about first, and it has a shape of its own. What a Midjourney prompt looks like when it comes from an image walks the ten slots in the order they appear and explains the one value at the end that never came off the measurement grid.
Download the full grid (CSV) — 480 rows, 40 images × 4 targets × 3 lengths, each row carrying that image'sedge measured at its own resolution, generated 2026-10-08
Twenty of those rows, with the measurements behind each line and the model it was written for, are laid out on image prompt examples.
Why the aspect value looks like that
The ratio is not a guess and it is not a lookup table of common sizes. It takes your dimensions, divides both by their greatest common divisor, and then scales them down if either side exceeds 60. A 640×360 frame divides cleanly by 40 and comes out as 16:9, untouched. An 800×450 frame divides by 50 and lands on the same 16:9. Both are ratios you would pick anyway.
The cap exists so that an odd crop does not emit something like 1913:977. The trade-off is that a frame whose true ratio does not divide neatly gets scaled to the nearest representable pair under 60, which is rounded rather than exact. All three samples here happen to divide cleanly, so none of them shows the effect — a screenshot cropped to an unusual width is where you will see it. Check the value before you generate.
What the three lengths drop and add
Length is not verbosity, it is which measured fields get included. At short, contrast, detail and lighting distribution are all dropped. At long, the vertical light phrase is added if one was measured, plus the mood phrase. These are the real strings for strong-backlight.png across all twelve combinations:
midjourney/short   (158) ... slightly warm tone --ar 16:9
midjourney/medium  (239) ... high contrast, moderate detail and texture, brighter
                          edges with a darker centre --ar 16:9
midjourney/long    (291) ... brighter upper half, moody and dramatic atmosphere
                          --ar 16:9
sd/short           (175) masterpiece, best quality, ... slightly warm tone
sd/medium          (256) ... brighter edges with a darker centre
sd/long            (308) ... brighter upper half, moody and dramatic atmosphere
flux/short         (105) A widescreen 16:9 image. Dark, low-key lighting. The
                         dominant colours are black, charcoal, silver, white.
flux/medium        (179) ... Vivid, saturated colour, slightly warm tone.
                         Moderate detail and texture.
flux/long          (247) ... Moderate detail and texture. Brighter edges with a
                         darker centre. Moody and dramatic atmosphere.
dalle/short         (98) A widescreen 16:9 image, dark, low-key lighting, with a
                         palette of black, charcoal, silver, white.
dalle/medium       (172) ... Vivid, saturated colour, slightly warm tone, moderate
                         detail and texture.
dalle/long         (203) ... moderate detail and texture. Moody and dramatic
                         atmosphere.
Read the top of that list before you reach for the long setting: the last 30 characters of the long variant are a mood phrase, and mood is the least reliable thing to add when you are trying to reproduce a specific picture rather than invent one. Medium is the useful default.
Feeding it back into your own tool
The generated order is deliberate and worth preserving. Subject comes first, framing second, palette third, then exposure, saturation, temperature, contrast, detail and lighting distribution. Because weight decays left to right in a Stable Diffusion checkpoint, having your subject at the front is the correct arrangement — do not shuffle it.
Three practical notes for the local case:
- Keep the quality tags if you are on a checkpoint trained with them. The Stable Diffusion variant already opens with
masterpiece, best quality,. If your checkpoint was not trained that way, they are dead weight at the front of the queue, pushing everything after them down — strip them. - The palette line carries four colour names with no weights. It sits in third position, ahead of exposure and contrast, so it is the highest-positioned term that is not your subject. If the render comes back over-coloured, it is the first thing to move, not the first thing to delete.
- Check whether a phrase is measured or inferred before you trust it. The subject field is only filled in when a threshold is actually crossed — monochrome share above 0.85, or green or blue dominance above 0.45 — and in those cases it is tagged as measured or inferred. Otherwise it stays empty and you are expected to write it. Every threshold and the values behind them are laid out in what an image to prompt tool actually measures.
The number to look at when a phrase looks wrong
Detail is decided by an edge-density measure against a cut-off of 7 and then one at 15. On these three, edge measured 22.50, 13.02 and 5.14 — above 15, between the two lines, and below 7 — so they came out highly detailed with intricate texture, moderate detail and texture and clean and minimal, smooth surfaces respectively. The closest any of them sits to a cut-off is 1.86. That margin is not a fixed property of your picture: measure the same backlit meadow at full resolution rather than on the 192 grid and edge reads 9.60 instead of 13.02. Crop tighter or resave with more compression and the figure moves with you. When a phrase looks wrong, that is the number to look at.
When the result still comes out wrong
Every edit above assumes the prompt describes your picture and the render is what went wrong. If the render is wrong, work the causes in order rather than rewording — checkpoint first, then the checkpoint's own published settings, then verb form, then weights, then term order. The full ranked list with the parser output behind it is in your image to prompt output is wrong. For the other direction, words in and picture out, see what actually decides the result in prompt to image.